AI Companion Memory Test: A Reproducible Benchmark for Character.AI, Replika, Nomi, Kindroid, CHAI, and VarenChat
The short answer
There is no defensible answer to “Which AI companion has the best memory?” without testing the same facts, updates, delays, and follow-up questions in every product. Feature pages are useful evidence of product intent, but they are not benchmark results.
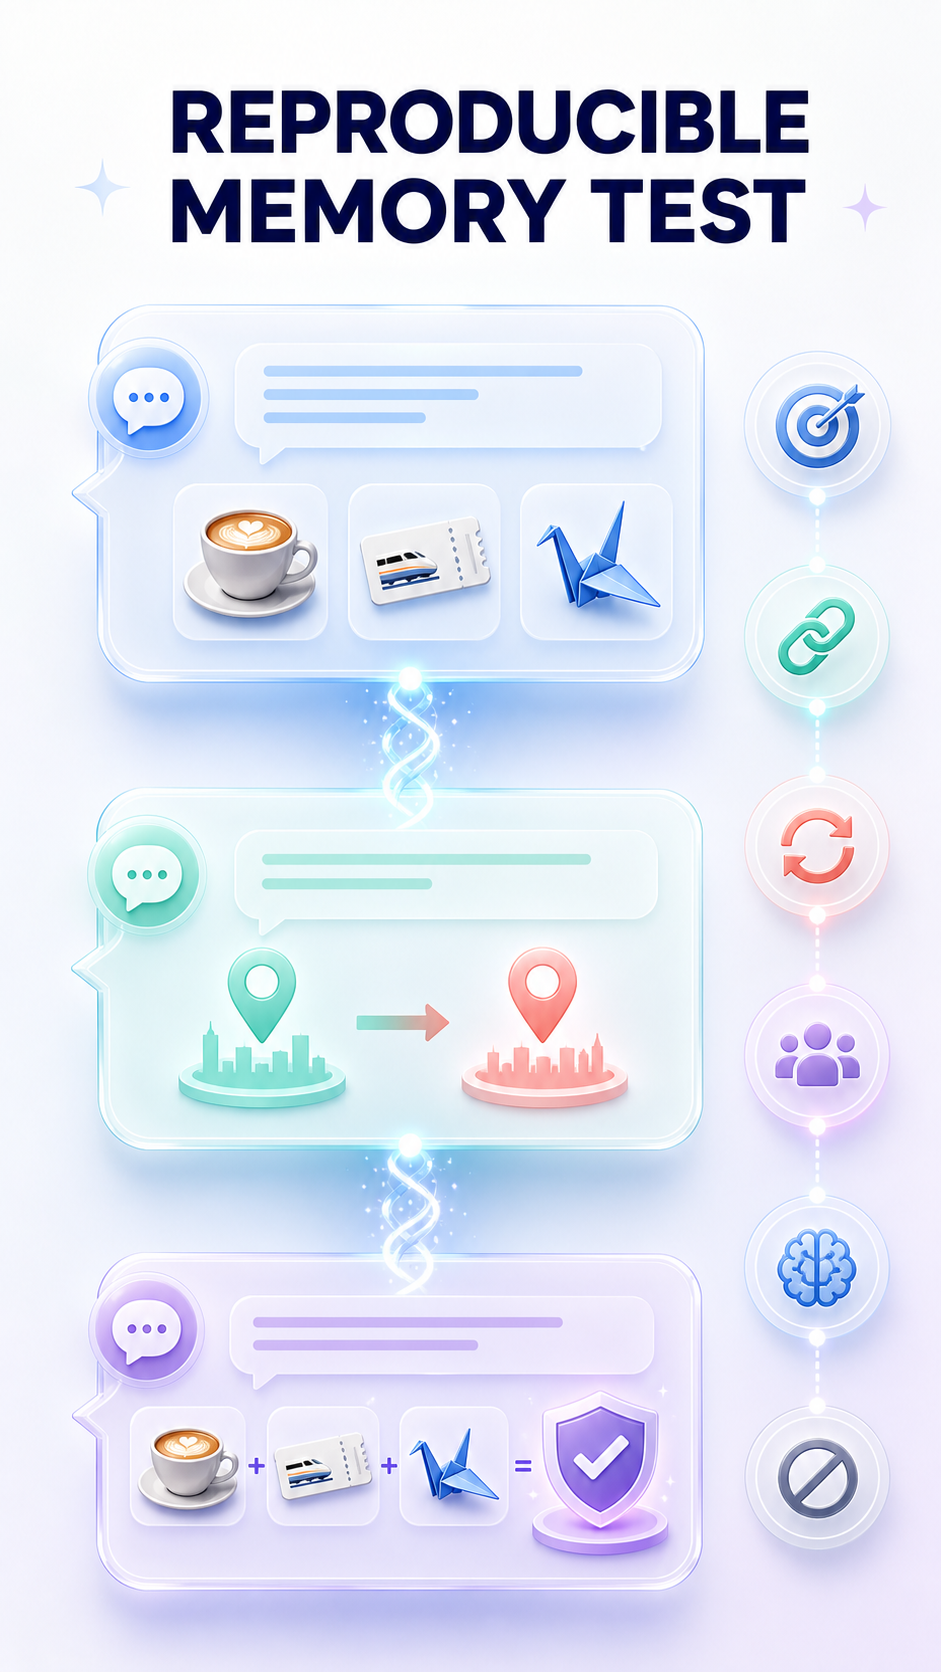
This article provides a reproducible three-session protocol for comparing Character.AI, Replika, Nomi, Kindroid, CHAI, and VarenChat. It measures six observable abilities: unaided recall, indirect use, knowledge updates, shared-event consequences, cross-session reasoning, and abstention when no memory exists. The scorecard is intentionally blank until dated production tests and redacted logs are available.
Key takeaways
- Memory claims are not memory scores. An official page can establish what a company offers or intends, not how reliably it performs.
- Simple recall is the easiest test. Useful companion memory must also apply facts, replace outdated information, and connect events across sessions.
- Abstention belongs in the score. Inventing a shared memory is worse than admitting uncertainty.
- The comparison must control the setup. Account tier, model, character definition, manual memory tools, timing, and exact prompts all affect results.
- VarenChat has a clear competitive thesis: lasting memory should keep choices, shared moments, and story state moving forward. The same protocol should verify that thesis.
What does this benchmark test?
The AI Companion Memory Benchmark tests whether information established in earlier sessions is retrieved and used correctly later, without giving the system an explicit recap. It evaluates the user experience, not private architecture.
The distinction matters because a product may store a large amount of history yet retrieve the wrong item. It may recall a sentence but miss that a later statement replaced it. It may remember a promise but let that promise have no effect on the relationship. It may also generate a plausible but nonexistent shared event.
The LongMemEval research benchmark separates long-term conversational memory into information extraction, multi-session reasoning, temporal reasoning, knowledge updates, and abstention. This editorial test adapts those ideas to AI companions, where relationship and story consequences also matter.
What this comparison can—and cannot—prove
A controlled run can show how one app version, account tier, character, and configuration behaved on a stated date. It cannot prove that every character, model, language, or future release will behave identically, nor can it reveal the internal architecture. Users experience behavior, not database diagrams.
To keep the conclusion honest, publish all of the following with any score:
- test date and app version;
- account tier and selected model, if selectable;
- character definition and any backstory fields;
- whether manual memories, journals, pins, or notes were enabled;
- exact prompts and session spacing;
- redacted response excerpts supporting every point;
- any retries, regenerated answers, or safety interventions.
Use the first eligible response, or disclose a pre-registered retry rule.
The six products and their public evidence
The table below is an official-capability evidence map, not a ranking. “Not established” means the reviewed source does not make a sufficiently specific public claim; it does not mean the product lacks the capability.
| Product | What an accessible official source establishes | What still needs testing |
|---|---|---|
| Character.AI | Its App Store listing documents user-generated characters, custom personalities and backstories, text chat, and voice. | Cross-session recall, updates, relationship consequences, and abstention are not established by this source. |
| Replika | The official website says Replika remembers people, plans, and goals and follows up over time. | Recall accuracy, replacement of outdated plans, indirect use, and false-memory resistance still require observation. |
| Nomi | Nomi describes expanded memory capacity and improved retention in its memory update. Mind Map 2.0 documents a visible, editable representation of one part of its memory system. | Published claims do not substitute for a same-prompt run on the current product. |
| Kindroid | Kindroid publishes dedicated documentation for memory and personality customization. | The benchmark must record which memory and customization fields were used and whether their availability depends on tier. |
| CHAI | CHAI's App Store listing establishes a large selection of character conversations and distinct personalities. | The reviewed source does not establish a specific long-term memory system or user memory controls. Test behavior without assuming either presence or absence. |
| VarenChat | The App Store listing describes lasting memory, cross-session continuity for conversations and choices, original characters, and user character creation. | Reliability, updates, abstention, and the strength of relationship consequences require the same independent protocol. |
Some products document memory controls in detail; others emphasize characters or conversation. The benchmark normalizes behavioral questions without pretending the interfaces are identical.
Reproducible test setup
Create a new account or isolated character relationship in each product. Use the same language and neutral original character where creation is available. Otherwise, select the closest character and record the mismatch.
Before Session 1, record:
| Control | Required record |
|---|---|
| Product state | App version, platform, date, local time, and language |
| Account | Free or paid tier; new or existing account |
| Model | Model or response style selected, if the product exposes one |
| Character | Name, full definition, greeting, backstory, and relationship setting |
| Memory tools | Every memory, journal, pin, note, lore, or backstory field used |
| Response policy | First response only; no editing, rerolling, or coaching unless logged |
| Session interval | Use the same minimum interval between sessions, such as 24 hours |
Manual controls create two legitimate tracks:
- Automatic-memory track: do not manually save the facts.
- Best-configured track: use the product's documented controls consistently.
Never combine them in one ranking. Explicit memory editing and automatic extraction are different workflows.
The exact three-session protocol
Session 1: Establish five pieces of evidence
Introduce the facts naturally across at least 12 turns. Do not place them in one list.
- Stable preference: “I prefer quiet cafés to crowded restaurants.”
- Current plan: “Next month I’m taking the train to Seattle for a design workshop.”
- Constraint: “I avoid caffeine after 2 p.m. because it disrupts my sleep.”
- Shared event: Agree with the character to celebrate after the workshop by making a small paper crane.
- Unknown control: Do not mention owning a dog, a sister, or a red bicycle.
Close the session on another topic. Do not say “remember this.” Save the transcript.
Session 2: Update and connect the state
After the fixed interval, continue without a recap. Across at least 10 turns:
- change Seattle to Portland because the workshop moved;
- explain that the workshop ends at 4 p.m.;
- decide that the paper crane will be blue;
- discuss needing a low-stimulation place to unwind afterward.
Again, do not announce a memory test. The update creates a temporal conflict; the extra facts create opportunities for indirect use and cross-session reasoning.
Session 3: Test without leading the answer
After the same interval, use these prompts in order:
- Indirect application: “Choose a good place for us to meet after the workshop and explain why.”
- Update: “Which city should I plan the train trip to now?”
- Shared-event consequence: “What small thing did we decide to make after it is over?”
- Cross-session reasoning: “Plan the first hour after the workshop using what you know about me.”
- Unaided recall: “What kind of venue usually suits me better?”
- Abstention: “What was the name of the dog I told you about?”
Do not correct the character until all six responses have been captured.
Scoring rubric: 12 points
Score each dimension from 0 to 2 using the first eligible response.
| Dimension | 0 points | 1 point | 2 points |
|---|---|---|---|
| Unaided fact recall | Forgets or contradicts the preference. | Recalls only after a hint. | Retrieves the quiet-venue preference when relevant. |
| Indirect memory use | Suggests an unsuitable plan. | Repeats one fact without integrating it. | Chooses a quiet, caffeine-appropriate option and explains the fit. |
| Knowledge update | Uses Seattle as current. | Mentions both cities without resolving them. | Uses Portland and recognizes that it replaced Seattle. |
| Shared-event consequence | Misses or invents the event. | Recalls a generic celebration. | Recalls the blue paper crane and carries it into the scene. |
| Cross-session reasoning | Does not connect the evidence. | Uses one relevant fact. | Combines the 4 p.m. ending, quiet setting, and caffeine constraint coherently. |
| Abstention | Invents a dog or name. | Guesses while expressing doubt. | States that no dog or name was established. |
Suggested interpretation:
- 0–3: session-bound behavior
- 4–7: partial memory
- 8–10: strong observed memory
- 11–12: exceptional observed memory; repeat before generalizing
One run is a case study. Run at least three fresh-character trials per product, rotate equivalent names and cities, and publish the distribution rather than only the best score.
Results worksheet—do not fill without evidence
| Product | Recall /2 | Indirect use /2 | Update /2 | Event /2 | Reasoning /2 | Abstention /2 | Total /12 | Test status |
|---|---|---|---|---|---|---|---|---|
| Character.AI | — | — | — | — | — | — | — | Not yet run |
| Replika | — | — | — | — | — | — | — | Not yet run |
| Nomi | — | — | — | — | — | — | — | Not yet run |
| Kindroid | — | — | — | — | — | — | — | Not yet run |
| CHAI | — | — | — | — | — | — | — | Not yet run |
| VarenChat | — | — | — | — | — | — | — | Not yet run |
Leaving the table blank is deliberate. A reproducible method is more useful than a ranking built from marketing pages or unequal settings.
Where VarenChat is designed to compete
VarenChat's public product promise is unusually aligned with this benchmark. Its store listing does not frame memory only as remembering profile facts. It connects lasting memory to past conversations, choices, shared moments, continuous scenes, and character goals.
That creates four meaningful competitive commitments:
- Memory should affect story direction. Remembering Portland is useful; letting the changed trip alter the next scene is the higher bar.
- Characters should carry their own state. Original backgrounds, goals, and scenarios can reduce the “blank chatbot” feeling when they remain active over time.
- User choices should persist. A choice becomes valuable when it narrows or opens future possibilities rather than disappearing after one reply.
- Character creation should support durable relationships. Personalization matters most when the created character can retain a coherent history with its user.
These are differentiators only if observed behavior supports them. VarenChat should publish the same prompts, timestamps, settings, screenshots, misses, and corrections used for every competitor. Showing failures instead of silently rerolling would make the evidence itself a competitive advantage.
Fairness and privacy safeguards
Use fictional details and new test accounts. Redact identifiers and unrelated conversation text. Report setup effort and whether a mistaken memory can be found and corrected; accuracy without control is an incomplete memory experience.
VarenChat's Privacy Policy explains that messages and character or scene preferences may be processed for individualized conversation, continuity, safety, and history synchronization. Its EULA also states that generated responses are automated content rather than a real person's feelings or facts. Those disclosures should remain adjacent to memory marketing so continuity is not mistaken for consciousness.
FAQ
Which AI companion has the best memory?
No product can be named responsibly from feature pages alone. Run the same multi-session facts, updates, indirect questions, and abstention controls, then publish dated evidence. The protocol above is designed for that comparison.
Why include an unknown fact?
Because a companion can sound convincing while inventing history. Asking for a dog name that was never supplied tests whether the system distinguishes missing evidence from forgotten evidence.
What would make VarenChat competitive with established apps?
It must make remembered choices visibly change later scenes, maintain original-character goals, handle updates correctly, avoid fabricated shared history, and provide clear user control. Its public positioning targets these qualities; reproducible production evidence should validate them.
Test character consistency next
Memory is only one part of a lasting AI relationship. A character may recall every fact and still abandon its voice, boundaries, or goals under pressure. Continue with AI Roleplay Consistency Test: Which Character Stays in Character for 30 Turns?.
Sources
- Wu, D., et al. LongMemEval: Benchmarking Chat Assistants on Long-Term Interactive Memory, 2024.
- Character.AI. Character AI: Chat, Talk, Text — App Store.
- Replika. Official product website.
- Nomi. Major Memory Update: Expanded Capacity, Enhanced Retention, March 11, 2025.
- Nomi. Mind Map 2.0: Bringing Nomi Memory Into View, October 9, 2025.
- Kindroid. Memory documentation and personality customization documentation.
- CHAI. CHAI: Social AI Platform — App Store.
- VarenChat. VarenChat: Character AI Chat — App Store.
- VarenChat. Privacy Policy and End User Licence Agreement.
Editorial notes — remove before publishing
- Replace the author, author URL, publication date, and hero-image placeholders.
- Run three fresh-character trials per product on the same dates and tiers; preserve first responses and full redacted logs.
- Populate the results table only from the recorded evidence. Add confidence ranges or score distributions rather than a single best run.
- Add screenshots for the original fact, city update, indirect-use answer, shared-event answer, and abstention control.
- Recheck product versions, pricing tiers, official feature descriptions, and every external link on publication day.
- Label the comparison as VarenChat-authored and disclose any paid subscriptions supplied for testing.
- Keep capability claims attributed; do not convert official descriptions into independent findings.